Organisations rarely lack data. They lack consistent definitions, dependable movement and confidence in the result. Data engineering creates value when it makes important information timely, explainable and useful for action.
Organisations collect large amounts of data but often struggle to turn it into decisions. Data engineering builds the pipelines, models and quality checks that make information trustworthy and available when leaders need it.
Our work connects scattered sources into a reliable platform where teams share one consistent understanding of key metrics.
Define the decision first
A pipeline should begin with the question or operational action it supports. This reveals which sources, freshness and quality levels matter. It also prevents teams from collecting large volumes of information without a clear purpose.
Create shared measures
Revenue, active customer and delivery time can mean different things across teams. Governed definitions, ownership and transformation logic reduce conflicting reports. Documentation should show where each measure comes from and how it changes.
Test data like software
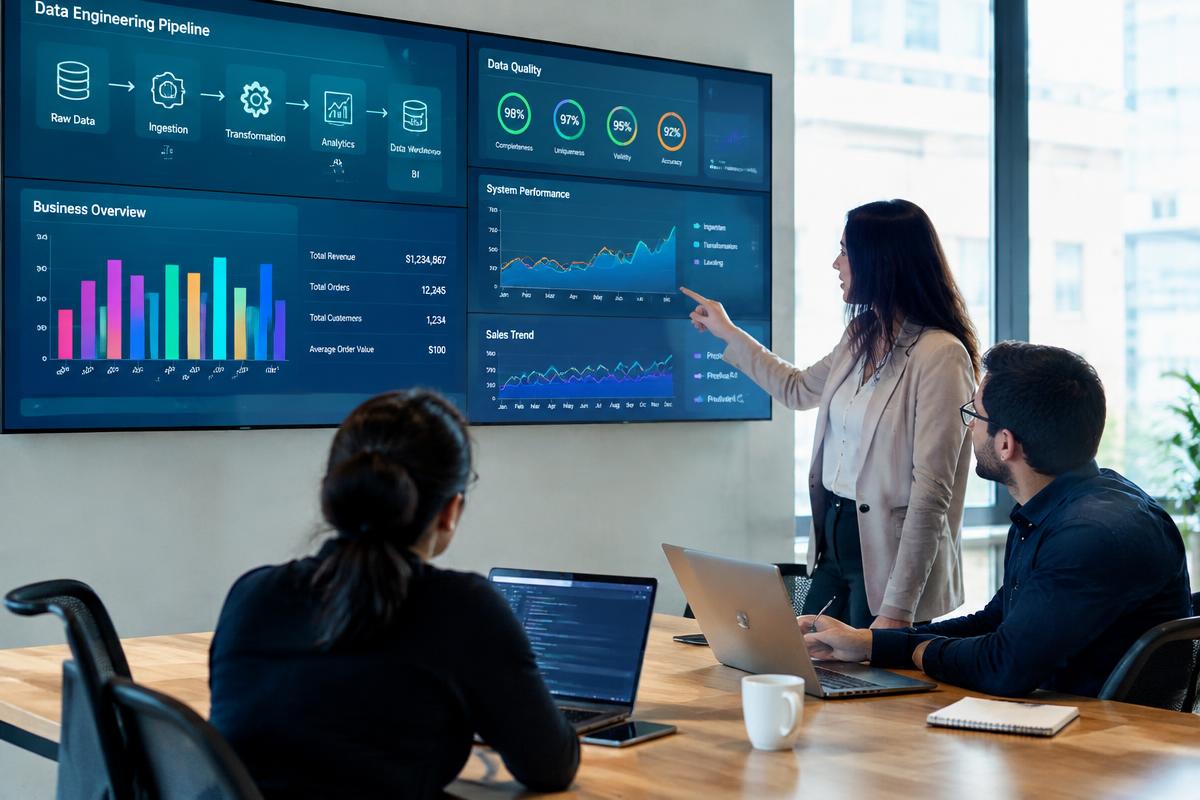
Pipelines need checks for completeness, validity, freshness and unusual change. Automated tests catch common failures, while clear lineage helps teams understand impact. Quality issues should reach the people who can act on them with enough context to respond.
Reliable ingestion
Data arrives from applications, partner systems, files and event streams. Ingestion pipelines should handle schema changes, late data and failures gracefully. Managed connectors reduce custom code for common sources such as payment and marketing platforms.
Modelling for understanding
Raw data is transformed into clean models with clear business definitions. Tools such as dbt allow transformations to be written in SQL, version controlled, tested and documented. A shared metric definition prevents different departments reporting different revenue numbers.
Data quality and trust
Automated tests check for missing values, duplicates, unexpected ranges and freshness. When a check fails, owners are alerted before dashboards show incorrect results. Trust in data is built slowly and lost quickly, so quality must be continuous.
Serving insight
Clean models feed dashboards, self service analytics, operational tools and machine learning. Dashboards should answer specific decisions rather than displaying every available chart. Good governance defines who can see which data and why.
Recommended technology
Tools we use and why
Snowflake
Scalable cloud data warehouse with simple operations.
Google BigQuery
Serverless analytics at very large scale.
dbt
Tested and documented SQL transformations.
Apache Airflow
Orchestration of complex data workflows.
Fivetran
Managed connectors for common business systems.
Power BI and Looker
Business intelligence dashboards and self service analysis.
Step by step approach
How we deliver it
- 1Identify the key decisions and the metrics that support them.
- 2Inventory data sources, owners and quality issues.
- 3Build ingestion pipelines into a central warehouse.
- 4Model data with shared definitions, tests and documentation.
- 5Deliver focused dashboards and self service access.
- 6Monitor freshness and quality with clear ownership.
Avoid these
Common mistakes
- Building a data lake without clear questions to answer.
- Letting each team define key metrics differently.
- Skipping data tests until executives notice wrong numbers.
- Creating dashboards that nobody uses for decisions.
Measure success
Key metrics
- Data freshness within agreed windows for key sources.
- Percentage of models covered by automated tests.
- Active weekly users of analytics tools.
- Time from new question to trusted answer.
Practical priorities
What technology leaders should carry forward
- Connect each pipeline to a decision
- Give important measures clear ownership
- Automate data quality and lineage checks
Questions answered
Frequently asked questions
Do we need a data warehouse?
Once data comes from several systems and decisions depend on combining it, a warehouse usually becomes the most reliable approach.
How long before we see value?
A focused first use case can deliver trusted dashboards within weeks, with the platform growing from there.
Who should own data quality?
Source system owners and data teams share responsibility, supported by automated checks and clear escalation.
SJ Dev Technologies perspective
Reliable data platforms create a common basis for decisions. Their value comes from shared meaning and operational trust, not simply from storing more information.